
Homegrown Malaysian AI
- 29
- years in BPO and digital services
- 20+
- open models
- 40+
- open datasets
- 6
- models in the Nusa Voice Stack
Most voice AI was never built for a Malaysian phone call.
It arrives at 8 kHz, squeezed through a codec designed in the 1970s. The caller switches from Malay to English to Hokkien inside a single sentence. They pause to think, and the agent talks over them.
On our Malaysian contact-centre test set, raw call audio transcribed by Whisper large-v3 gives the starting point below. Everything after it is what we built to fix it.
71.48%
Character error rate, raw 8 kHz call audio
Malaysian contact-centre corpus, held outMeasured Source(opens in a new tab)
Lower is better.
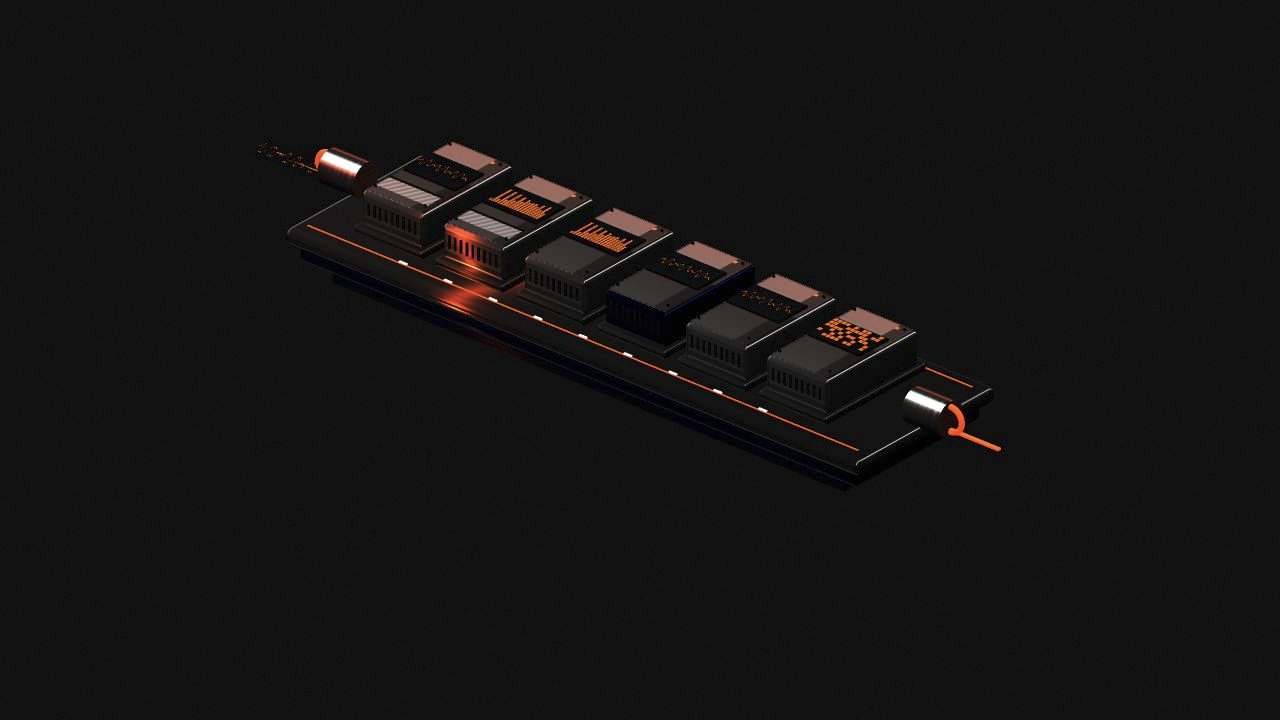
Scicom's Nusa Voice Stack:6 enterprise models we built
- caller audio, 8 kHz
- agent audio, out
Nusa Voice Stack is six models covering the voice path from caller audio to agent audio. Not an orchestration layer over other people's APIs. We trained the models ourselves, and some build on open pretrained models, listed below. When the data or the failure mode changes, we can retrain the model.
Built on: w2v-BERT 2.0 and DAC (Nusa Enhance), Whisper (Nusa Turn Detector, Nusa STT), Qwen3 and NeuCodec (Nusa TTS), NeuCodec (Nusa Codec).
Get these wrong and the caller hangs up.
Hear the caller, not the phone line
Nusa Enhance takes 8 kHz telephony audio and outputs it at 48 kHz before transcription. The small model is downloadable; the larger enterprise model is licensed instead.
Every system below was run on the same held-out contact-centre set and scored the same way, including the open restoration models we did not build.
19.01%
Character error rate, enterprise enhancement model
Malaysian contact-centre corpus, held outMeasured Source(opens in a new tab)
Down from 71.48% on the raw call audio. Lower is better.
| System | Character error rate (%) |
|---|---|
| Nusa Enhance, enterprise — Scicom | 19.01% |
| Nusa Enhance Small — Scicom | 38.91% |
| sidon-v0.1 | 41.06% |
| resemble-enhance | 54.96% |
| voicefixer | 58.27% |
| Raw 8 kHz call audio, no processing | 71.48% |
Stop interrupting people
The problem is deciding when a caller has actually finished speaking, not simply detecting silence. Nusa Turn Detector reads the last eight seconds of audio and decides whether the caller is finished, with no transcript, on a single CPU thread.
20.0%
False cutoff rate at a 0.6 s budget
300 recorded Malaysian telephony turnsMeasured Source(opens in a new tab)
How often the enterprise model cuts a caller off. Lower is better.
| System | False cutoff rate (%) |
|---|---|
| Nusa Turn Detector, enterprise — Scicom | 20.0% |
| Nusa Turn Detector, downloadable — Scicom | 22.1% |
| LiveKit cloud detector — LiveKit | 27.8% |
Sound like a person, in any language
One TTS model, 76 evaluated languages, any speaker in the set, with delivery controlled by a written description.
Systems covering fewer languages score higher over their own subsets, so this comparison holds only at 76-language coverage.
3.233
Predicted naturalness across 76 languages
76 evaluated languagesMeasured Source(opens in a new tab)
A predicted opinion score out of 5. Higher is better.
| System | faster-UTMOSv2 |
|---|---|
| Nusa TTS — Scicom | 3.233 |
| Fish Audio S2 Pro — Fish Audio | 2.9698 |
| Orpheus | 2.7267 |
| Dia | 1.8575 |
In production at 
At TM, we built the models, deployed them into the contact centre, and run them there.
- 3B+
- tokens processed, and counting
From bare metal to the live call.
We build your AI, connect it to your systems, and keep it running.
- 01
Build
Infrastructure and models, fitted to your business.
- 02
Deploy
Connected to your telephony, CRM and tools.
- 03
Run
Live conversations, monitored and continuously improved.
Test it on your own audio this afternoon.
Download a model and run it against your own calls. Or send us a recording and we will run the whole pipeline on it.