Tech Blog
How we size voice agents for enterprise traffic
The load testing tool we built, what the measurements showed, a scheduling bug that took us too long to find, and the Erlang model we now use for sizing.
Press releases, papers, research and platform releases, and engineering posts from Scicom's AI team.
The load testing tool we built, what the measurements showed, a scheduling bug that took us too long to find, and the Erlang model we now use for sizing.
Our technical report fine-tunes whisper-large-v3 on the phrases it invents, spoken for real. On real audio with no speech in it, the share of clips where it writes words falls from 99.9% to 47.8%, while recovery of genuinely spoken phrases rises from 69.8% to 82.7%.
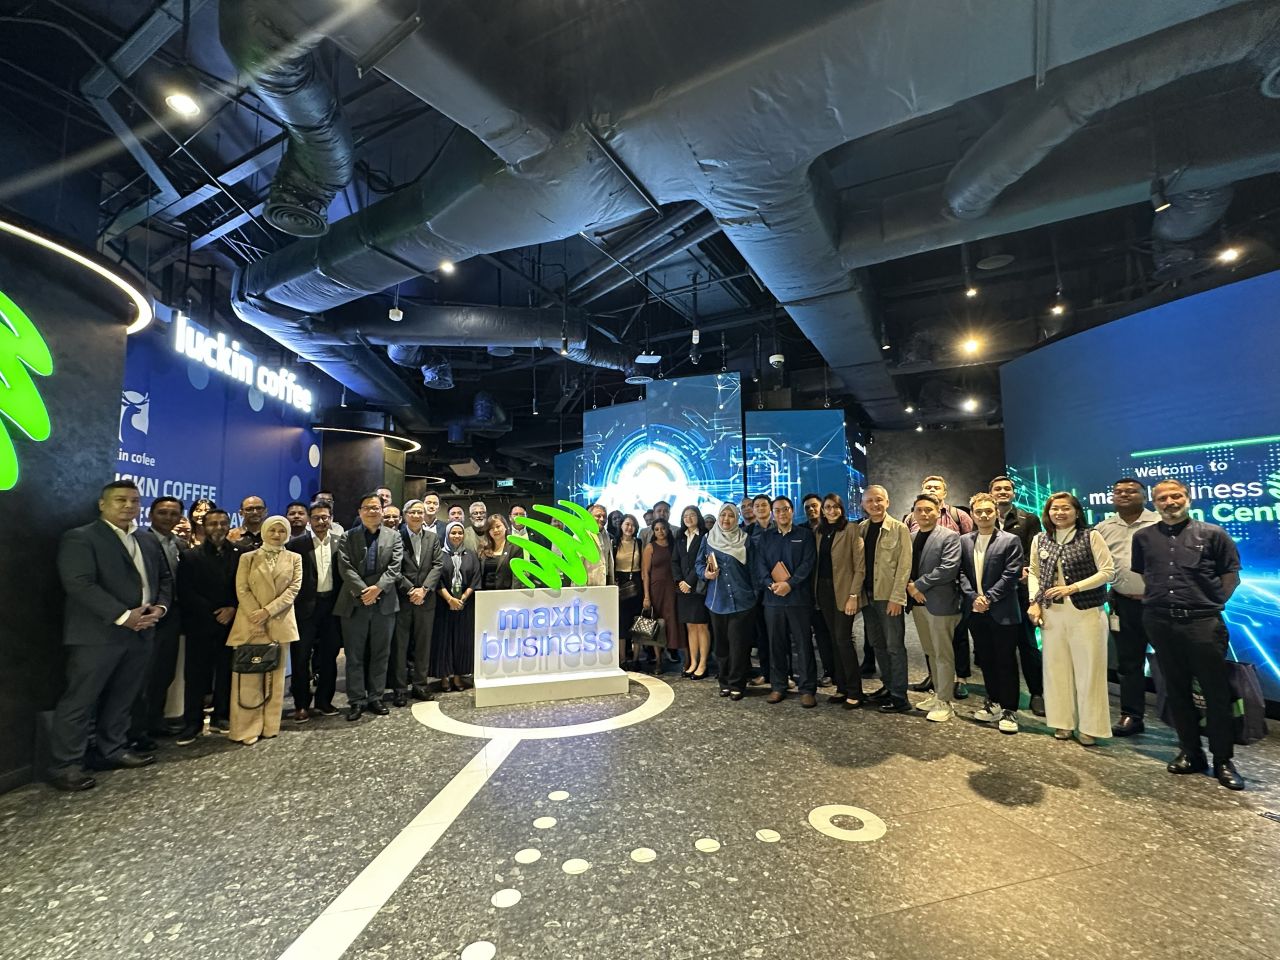
Scicom's Senior Vice President of AI Enterprise Solutions joined a panel of industry leaders on how artificial intelligence and data are reshaping enterprise customer experience across Malaysia.
2 min read
arXiv 2609.32560
Our technical report fine-tunes whisper-large-v3 on the phrases it invents, spoken for real. On real audio with no speech in it, the share of clips where it writes words falls from 99.9% to 47.8%, while recovery of genuinely spoken phrases rises from 69.8% to 82.7%.
Husein Zolkepli
47.8%
Real voice-free clips where the best fine-tune emits words, down from 99.9% for whisper-large-v3
Wild test split, 4,421 clips with no speech by Silero VADMeasured Source(opens in a new tab)
82.7%
Genuinely spoken hallucination phrases the best fine-tune recovers, up from 69.8% for whisper-large-v3
lexicon_synth test split, 6,267 clips in 83 languagesMeasured Source(opens in a new tab)
arXiv 2601.20185
Our paper on arXiv changes two settings in the open X-Codec-2.0 speech codec. It now uses 25 tokens a second instead of 50, outputs 24 kHz audio instead of 16 kHz, and scores higher on predicted naturalness across 116 languages.
Husein Zolkepli
+0.29
Predicted naturalness gain over X-Codec-2.0, at half the token rate
Common Voice 17 test set, 116 languagesMeasured Source(opens in a new tab)

False cutoff rate across ten end-of-turn systems at two latency budgets, measured over 300 real call turns on Malaysian telephony. The lowest of any system we tested, at both.
1 min read

Our open source speech enhancement model cuts character error rate on a private call centre set from 71.48% to 19.01%. Here is what we are building on top of it.
1 min read
A single codebook at 50 tokens per second, scored against four other 44 kHz-class codecs on a 9,291-clip multilingual wideband set.
1 min read
Cluster configuration, node bootstrapping, a browser terminal, job insights and proxy exposure, without the terminal windows and SSH configs.
1 min read

The load testing tool we built, what the measurements showed, a scheduling bug that took us too long to find, and the Erlang model we now use for sizing.
15 min read
